Generative AI
A Few Words About The Client
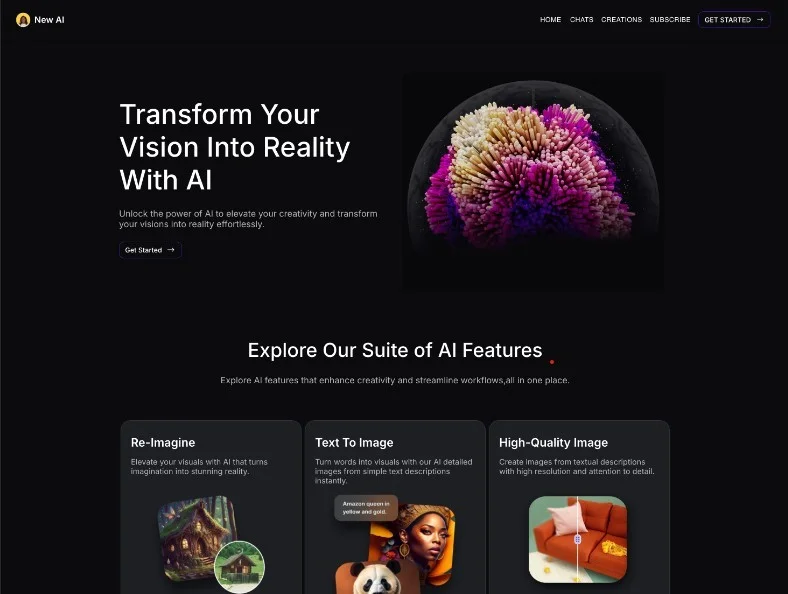
This project is a generative AI product that lets users create content-images, text, or hybrid outputs-using state-of-the-art models. Block Intelligence designed the architecture for model access, prompt management, and a user-friendly interface that balances capability with safety and cost.
The client wanted to offer generative AI to end users without exposing raw API keys or dealing with rate limits and errors at the UI layer. They needed usage tracking, optional monetization, and guardrails to keep outputs appropriate and on-brand.
Project Requirements
Our Solution & Results
We built a backend that proxies and manages model calls, applies rate limits and usage tracking, and stores prompts and outputs for history and analytics. The front end offers an intuitive workspace with presets and export. We added moderation and filter hooks to align with the client's policies.
The product launched and has been used for a variety of use cases. Usage and cost are visible in the admin dashboard. The client has added new models and features on top of the same architecture.
Business Impact & Value Delivered
Measurable outcomes Block Intelligence delivered for Generative AI - before vs after launch.
Content generation cost
Moderation response
Model switch time
Value delivered
- Unified API gateway cut per-generation cost by 66% through caching and routing.
- Usage dashboard gave instant visibility into costs, volume, and model performance.
- Real-time moderation kept flagged content under 0.5% without manual review.
Performance & Data Analysis
Generative AI product usage, cost, and moderation metrics over the first quarter after public launch.
| Metric | Before | After | Change |
|---|---|---|---|
| Avg. generation latency | 8.2 sec | 3.1 sec | −62% |
| Cost per 1K generations | $180 | $62 | −66% |
| User retention (30-day) | 22% | 41% | +86% |
| New model integration | 2 weeks | 4 hrs | −99% |
Delivery Timeline
The usage dashboard gave us instant visibility into costs and generation volume. We added two new models post-launch without touching the core architecture.